When search engine crawlers like Googlebot visit your website, their goal is to index unique, high-value pages that provide distinct answers to user queries. If your website unintentionally serves identical or near-identical content across multiple URLs, you run into one of the most common and damaging technical SEO issues: duplicate content.
Duplicate content confuses search engines. When Google encounters the same paragraphs or product descriptions across three or four different URLs, it cannot decide which page deserves to rank. As a result, search engines may split your ranking power (link equity), waste your crawl budget on redundant pages, or in severe cases, filter your pages out of search results entirely.
For businesses operating in Kenya and across East Africa, maintaining a clean URL structure is essential for outranking competitors. At Black Shepherd Technologies, our technical audits frequently uncover hidden duplicate content traps. In this comprehensive guide, we explore what causes duplicate content, how it harms your SEO, and how to master canonical tags to protect your rankings.
1. What Is Duplicate Content and Why Does It Happen?
Duplicate content refers to substantial blocks of content within or across domains that either completely match other content or are appreciably similar.
While Google does not issue a manual “penalty” for duplicate content unless it is blatantly plagiarized to manipulate search results, duplicate URLs create severe algorithmic hurdles.
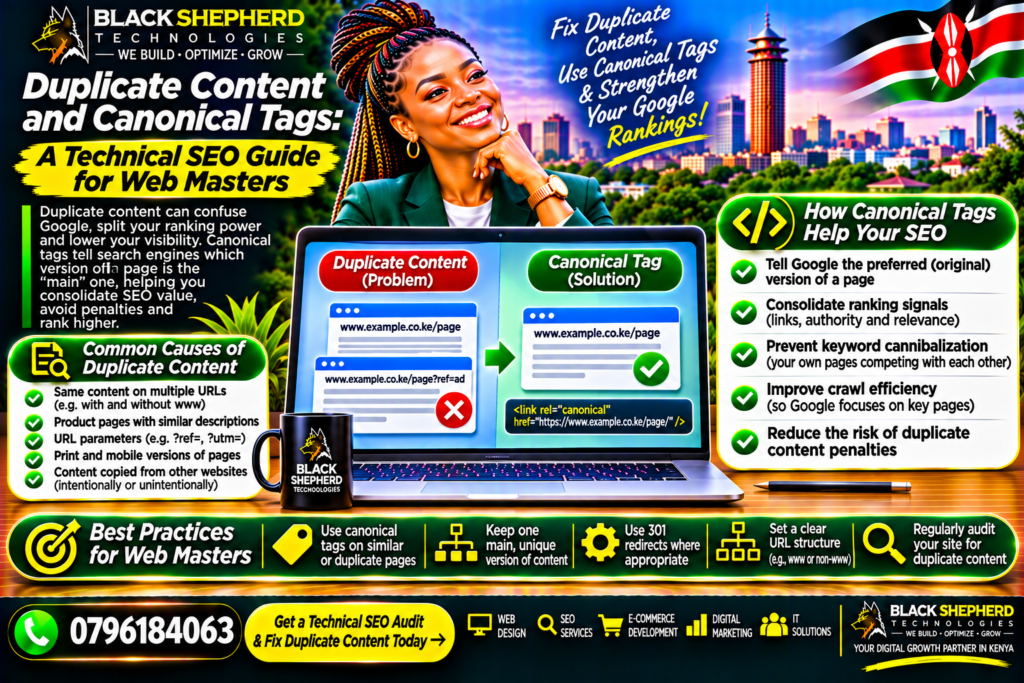
Common Causes of Duplicate Content on Websites:
-
Protocol and Domain Variations: Your website is accidentally accessible via four different URLs:
[http://yoursite.co.ke](http://yoursite.co.ke),[https://yoursite.co.ke](https://yoursite.co.ke),[http://www.yoursite.co.ke](http://www.yoursite.co.ke), and[https://www.yoursite.co.ke](https://www.yoursite.co.ke). To a human, these are the same site; to a search crawler, they are four distinct sites with identical content. -
E-Commerce Faceted Navigation and Sorting: Online stores often generate multiple URLs for the exact same product based on user filters (e.g.,
shop.co.ke/shoes?color=redandshop.co.ke/shoes?size=9&color=red). -
Trailing Slashes and Uppercase/Lowercase Letters: URLs like
yoursite.co.ke/servicesandyoursite.co.ke/services/(or mixed casing) can sometimes resolve to separate pages. -
Printer-Friendly or Mobile Subdomains: Separate pages created for print layouts or legacy mobile subdomains without proper redirection.
2. Why Duplicate Content Destroys Your SEO
When unmanaged, duplicate content triggers a chain reaction of negative technical SEO consequences:
-
Keyword Cannibalization: Your own web pages compete against each other for the same search keywords, diluting your domain authority and preventing any single page from securing Page 1 rankings.
-
Crawl Budget Exhaustion: Search bots waste precious time crawling hundreds of faceted filter URLs instead of discovering your new blog posts or high-value service pages.
-
Diluted Link Equity: If external blogs link to version A of your page while others link to version B, your valuable backlink authority is split rather than consolidated.
Explore our engineering standards in our portfolio and projects showcase to see how we structure clean, error-free digital architectures for complex web builds.
3. The Ultimate Solution: Master Canonical Tags
A canonical tag (rel="canonical") is a snippet of HTML code that tells search engine crawlers which version of a URL is the master, preferred copy. By implementing a canonical tag, you tell Google: “Even though this page is accessible via multiple URLs, treat this specific URL as the definitive original source.”
How Canonical Tags Work in Code
If you have a product page accessible via a messy tracking URL, you place a canonical tag inside the <head> section of that duplicate page pointing to the clean master URL:
<link rel="canonical" href="https://blackshepherd.co.ke/kenya/seo-services-kenya/" />
4. Best Practices for Implementing Canonical Tags
To ensure search engines respect your canonical tags, follow these gold standards:
-
Self-Referencing Canonicals: Every unique primary page should include a canonical tag that points to itself. This protects your page from being accidentally scraped or indexed under query parameters.
-
Absolute URLs vs. Relative URLs: Always use absolute URLs (
[https://yoursite.co.ke/page](https://yoursite.co.ke/page)) rather than relative URLs (/page) inside your canonical tags to eliminate ambiguity for crawlers. -
Match Canonical URLs with 301 Redirects: If a page is entirely redundant, use a permanent 301 redirect rather than a canonical tag. Reserve canonical tags for pages that must remain accessible to users (like e-commerce filter pages) but need to pass SEO value to a parent URL.
-
One Canonical Per Page: Never place multiple canonical tags in the header of a single web page, as conflicting tags will cause search engines to ignore them entirely.
5. Other Powerful Ways to Prevent Duplicate Content
While canonical tags are your primary weapon, a robust technical SEO strategy requires a multi-layered defense:
-
Enforce Strict Redirect Rules: Configure your server (.htaccess or Nginx configuration) to force all traffic to a single preferred domain version (
https://withwwwor non-www). -
Optimize Robots.txt and Meta Robots: Use
noindex, followtags on low-value internal search result pages or parameter-heavy archive pages to keep them out of Google’s index. -
Tailor Content Across the [Industries We Serve]: Whether building portals for real estate, fintech, or retail across the industries we serve, ensure that service descriptions are uniquely written rather than copy-pasted across different regional landing pages.
6. Partnering with Experts: Why Black Shepherd Technologies Leads the Way
Managing complex canonical structures, URL parameters, and technical redirects requires meticulous engineering precision. A single misconfigured canonical tag can inadvertently de-index your most profitable revenue-generating pages.
At Black Shepherd Technologies, we combine advanced technical audits with flawless web architecture design. Whether you are scaling an enterprise e-commerce platform or structuring a multi-location corporate site, our team ensures your technical foundation is pristine.
Conclusion
Duplicate content is an invisible anchor holding back your website’s true ranking potential. By understanding the root causes of URL duplication and deploying proper canonical tags, 301 redirects, and clean site architecture, you consolidate your authority and give search engines a clear path to your best content.
Ready to eliminate duplicate errors and secure top-tier search rankings? Reach out to the experts at Black Shepherd Technologies today for a comprehensive technical SEO audit.